Research / Organisation design
Central AI Team, Embedded Teams, or a Federated Model?
Compare central, embedded, and federated AI teams by delivery ownership, standards, budgets, and support. Use a practical decision test for your company.
When several departments want AI at once, the question soon becomes who builds it and who keeps it working. A central AI team can concentrate scarce engineers and set common rules. Embedded teams know the work and can change it directly. A federated model gives business teams more control while a shared group maintains standards. Your choice determines where requests wait, who pays for production, and who answers when a system fails.
What the three models mean
Suppose a company wants AI to help with customer refunds, sales proposals, and supplier invoices. These workflows use different records and have different costs when the system gets something wrong. A team structure needs to make each workflow accountable without building a separate security and monitoring system three times.
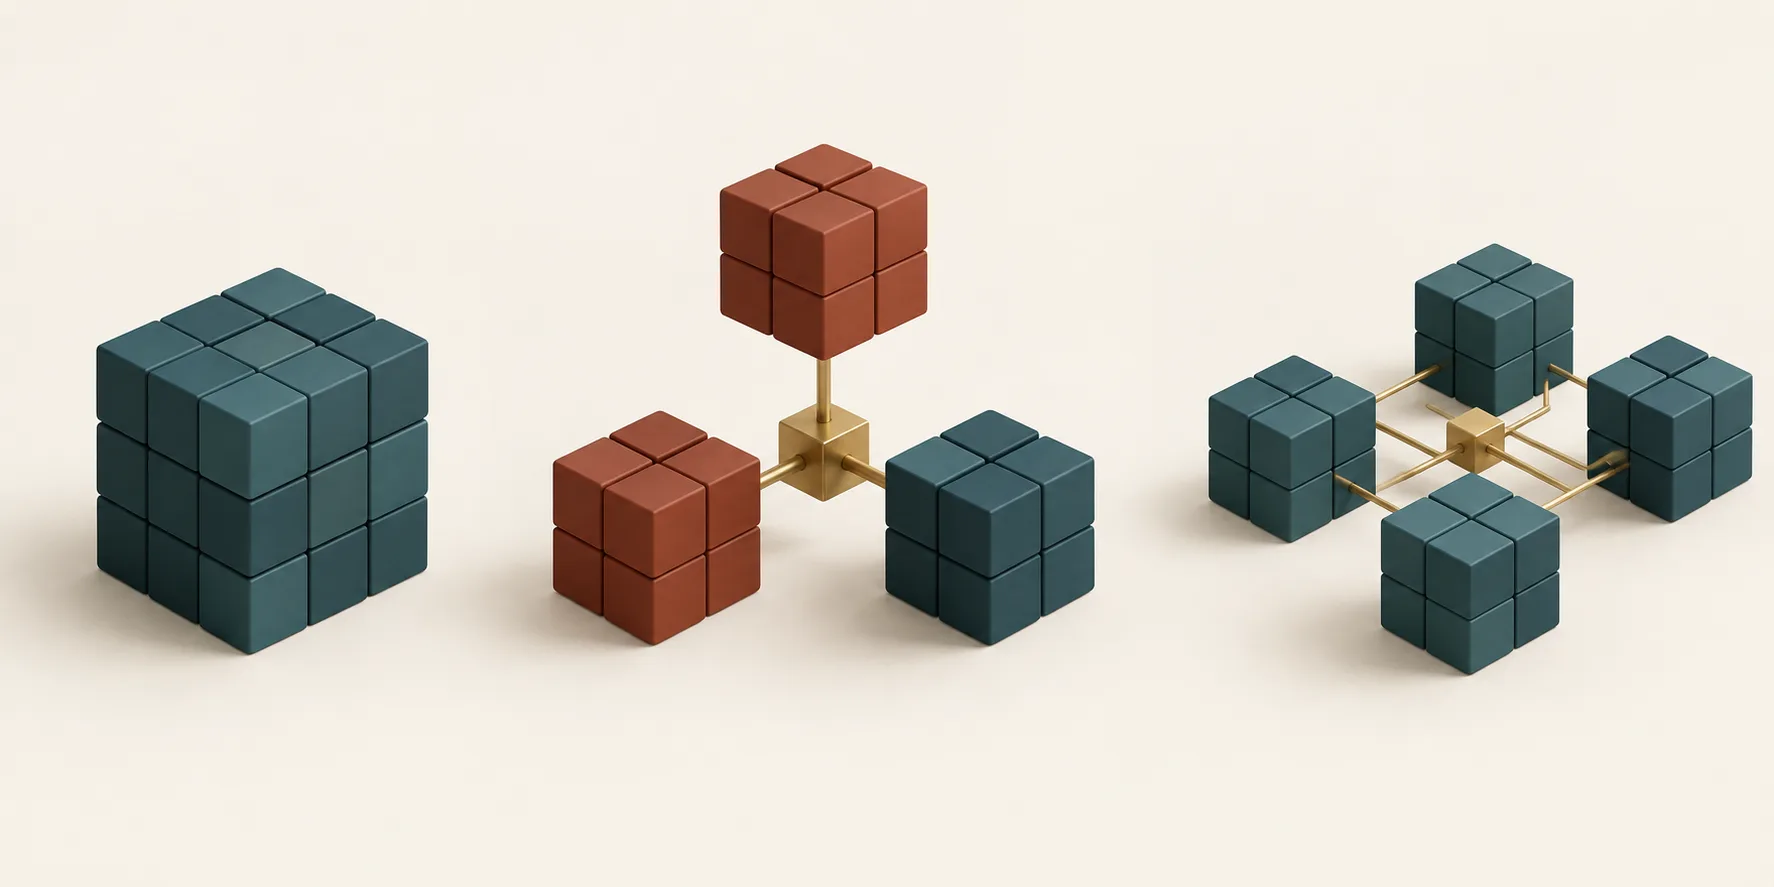
- Central: A shared AI team selects tools, builds workflows, sets standards, and runs them after launch. Departments supply process knowledge and approve the business outcome.
- Embedded: AI specialists work inside product or operations teams. Those teams choose, build, and run their own workflows, while company-wide security and data rules still apply.
- Federated: A small central group supplies a platform, standards, and expert help. Business teams own delivery and day-to-day operation within those limits. The center reviews exceptions and higher-risk work.
These are ways to assign work, not fixed organisation charts. Microsoft's guidance on AI operating models compares central, hybrid, and federated structures and notes that a company may use different arrangements for different kinds of work. The important test is whether the people named as owners can actually build, review, and support what runs.
When a central team earns its place
Central delivery fits a company with a small pool of AI engineers, little production experience, or several teams asking for the same basic capability. One group can establish approved model access, identity controls, evaluation methods, and a record of deployed systems. It can also stop three departments from buying separate tools to solve the same problem.
The cost is a queue. If the central team has to learn each refund rule, sales approval path, and invoice exception before it can make a change, local staff wait for work they understand better. A central team also needs a business owner for every workflow. Otherwise it may deliver a technically sound tool that no department has the time or budget to adopt.
Use a central model for the first few production workflows when specialists are scarce or the consequences of a bad release are high. Give each request a named sponsor, a process owner, a service target, and a date when the team will revisit ownership. Track how long requests sit in the queue. A growing queue with repeatable controls is a sign that delivery can move outward.
When to put specialists in business teams
An embedded engineer sits with the people who own a workflow. They can see the exceptions in real cases, test changes with staff, and fix a poor handoff without waiting for a central project slot. This works well when a product or operations team already owns its software, its budget, and its support rota.
The risk is duplication. Separate teams may pick different vendors, define customer data differently, or build their own logging and evaluation. Embedding also fails if you give one engineer to a business unit but leave them without technical review, access to production systems, or anyone to cover an incident. Keep a shared engineering community and a few mandatory platform rules even when delivery sits with local teams.
For the refund example, the customer-service team can own the policy checks and staff interface. The shared security team still sets access rules for order and payment data. Finance approves changes that affect the ledger. Local ownership means quicker decisions inside a clear boundary; it doesn't give a department sole authority over every system it touches.
What federation asks of each team
A federated model divides the work deliberately. The center publishes a supported route to production: approved services, identity, logging, evaluation standards, release checks, and an incident path. Each business team selects problems, provides domain knowledge, builds or configures workflows, measures results, and runs them. The center helps with exceptions and changes to shared infrastructure.
Federation needs more than permission to build. A business team must have the people and budget to maintain prompts, integrations, test cases, and review rules after launch. If it can't watch quality or respond to failures, the center will inherit the work by default. Microsoft's role and decision-rights guidance separates central standards from domain choices and calls for named people rather than an unassigned department label. That split is especially important when an AI system can take actions in other systems.
For a larger company, the refund and invoice teams can use the same platform and monitoring while owning different decision rules. A regional business with one small IT group may call its arrangement federated, but if that IT group still builds and supports every workflow, the operating model remains central in practice.
Decide who pays and who supports the work
A team diagram is incomplete until it names the budget and support owner. Write down who pays for shared infrastructure, model use, integration work, and the people who review results. Then name who answers a staff report, who investigates a data or model failure, and who can pause automated actions. NIST's AI Risk Management Framework calls for clear roles and communication in AI risk management, along with executive responsibility for risk decisions.
A practical split is for the center to fund and support common services while each business unit funds its workflow and owns its outcome. That split works only if the local budget covers ongoing review and maintenance, not merely the launch. For a shared workflow used by several units, appoint one accountable service owner and agree how the users will fund changes. Don't leave incident response to whichever engineer happens to be online.
Record six decisions for each production workflow: who selects the use case, who approves data access, who builds it, who accepts release risk, who pays to run it, and who handles an incident. The same person can hold several roles in a small firm. The answer to each question still needs a name.
Choose for the work you have now
Start by counting the workflows that need production support, the teams able to own that support, and the requests waiting on shared specialists. If only a few workflows exist and expertise is concentrated, central delivery keeps the work manageable. If a mature business team already owns the full software lifecycle, embed AI specialists there. If several capable teams need similar controls, use a federated model with a central platform and local delivery.
Risk can change the answer for a specific workflow. A low-risk drafting assistant may belong with a local team, while a system that issues refunds or changes supplier payments needs tighter release and action controls. Review the split every quarter: queue time, duplicated work, production incidents, staff adoption, and the cost of supporting each workflow tell you whether ownership is helping. Change the model when those measures change, not because a new chart looks cleaner.
For a startup or small company, name owners before creating a dedicated AI department. For a larger company with many teams, make the shared platform and support route real before giving each unit production autonomy. In either case, the design succeeds when the team closest to the work can improve it and the company can still see, govern, and support what runs.