Research / Change management
How to Choose AI Pilot Teams Without Creating Resentment
Choose AI pilot teams with clear criteria, protected learning time, manager support, and a fair path for other teams to participate next.
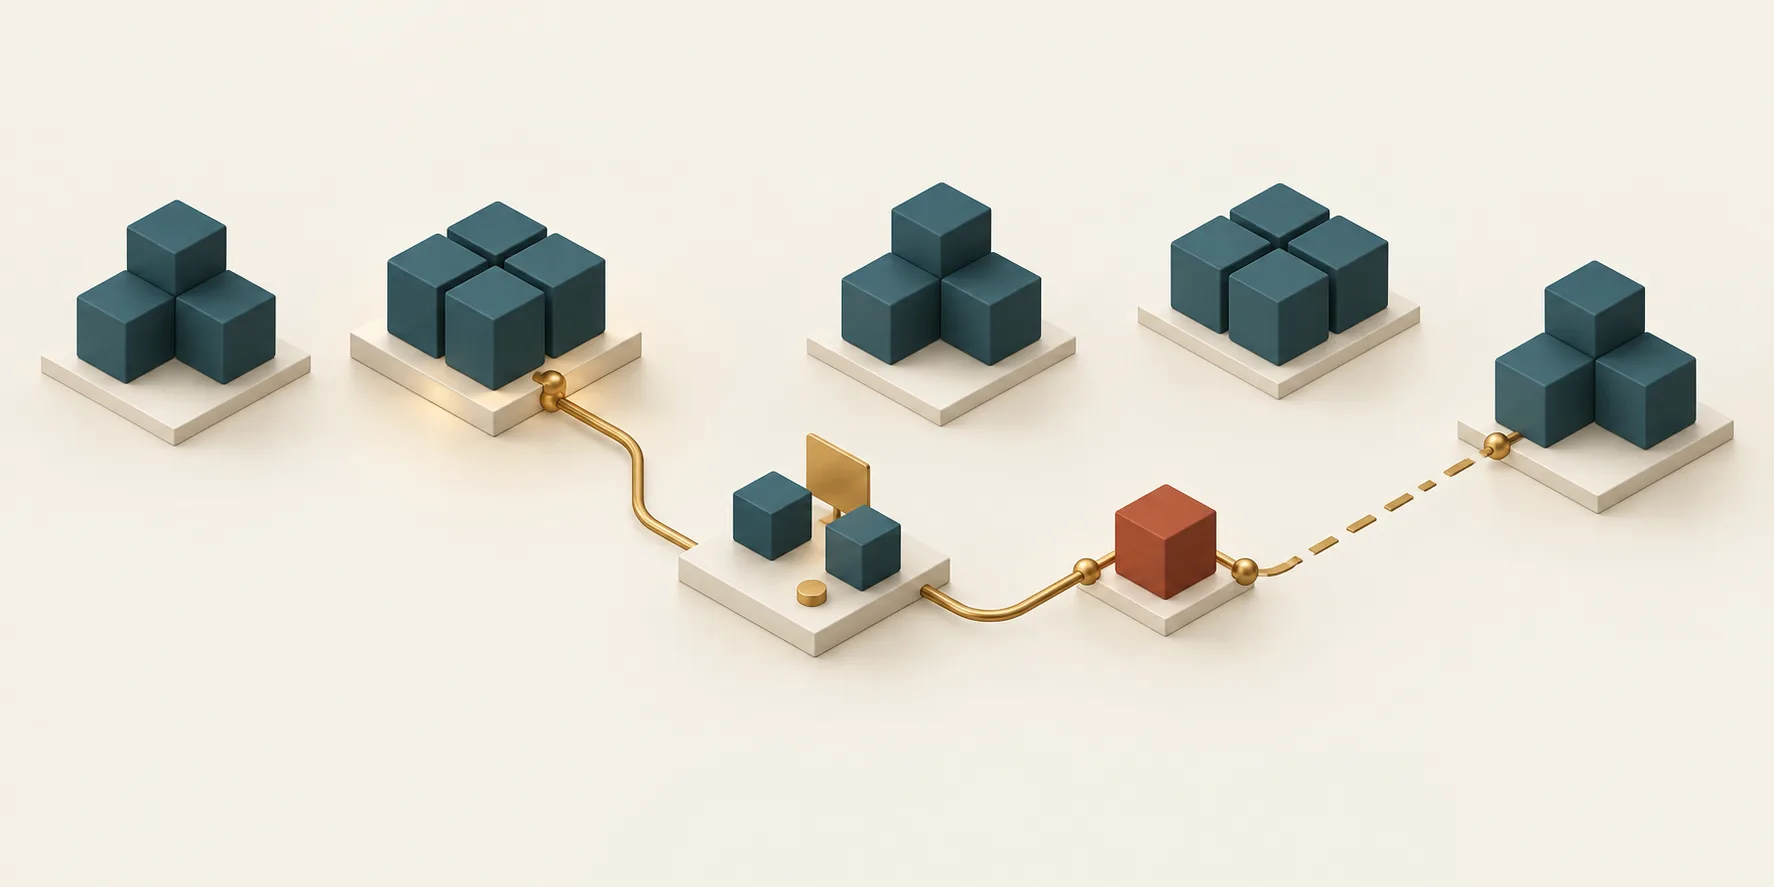
An AI pilot gives a few teams early access to a new way of working. If you choose them behind closed doors, other teams may see a reward, a threat, or a decision already made about their jobs. Choose teams against published criteria, give them time and support to test the work, and tell everyone what will happen after the pilot.
Set the question before choosing people
Write down what the pilot must learn. “Does this assistant reduce the time needed to resolve routine supplier queries without increasing corrections?” is a question you can test. “Can we get people excited about AI?” gives you little basis for choosing a team or deciding whether to continue.
Define the workflow, the people who do it, the case types that qualify, the risks that rule a case out, and the period you will observe. A team that handles enough comparable cases can show whether the process works. A senior executive's favourite team may have little of the work you need to study.
Include staff and their representatives early enough to change the pilot design. The OECD's AI workplace case studies describe how worker consultation helped organisations explain what systems did and how duties would change. Ask the people who handle exceptions which cases the tool should avoid and what evidence they need to check its output.
Publish selection criteria
Start with a short list of eligible teams. Score them against criteria tied to the question, and show the criteria before inviting nominations. For a customer-service pilot, the list might include a steady volume of the relevant requests, access to approved data, a manager who can release staff for training, and a mix of experienced and newer employees. Record why a team qualifies or does not.
Don't use enthusiasm as the only gate. Volunteers can tell you whether the tool works for motivated staff, but that may not predict what happens across the company. The UK Competition and Markets Authority's guidance on experiments explains that people who select themselves into a test can differ from those who don't. Invite volunteers, then select eligible teams so the pilot also covers ordinary levels of confidence, workload, and support.
If several teams meet the criteria, choose among them by a stated method. You can draw lots within an eligible group, select a pair with different workloads, or stage teams in a published order. Explain the method and any exceptions. A small company may have only one eligible team; saying so is clearer than dressing that decision up as a competition.
Check who your criteria exclude. Shift workers may have the same tasks as office staff but fewer chances to attend training. A remote team may have the volume you need but slower access to support. Change the support plan where you can, and note where the pilot will not represent the wider organisation.
Make participation workable
A pilot is extra work at first. People learn the tool, compare outputs with source records, report mistakes, and keep customers or colleagues served. Put those hours in the plan. Reduce ordinary targets for the pilot period or backfill part of the queue. If a manager says staff can experiment only after finishing their normal work, the test will measure spare time rather than the tool.
Give each team a named manager and a person who can resolve tool and data problems. The manager schedules paid learning time, sets the cases staff may use, and makes it safe to stop when the system produces a doubtful answer. The support owner responds to errors and records fixes. Agree on a response time for blocked cases so staff aren't left holding work while someone decides who owns the issue.
Tell participants how you will use their feedback and work data. Report on case quality, handling time, review effort, and problems with the workflow. Don't turn individual prompt counts or early mistakes into a performance ranking. People need to be able to describe failures without worrying that honesty will count against them. The OECD's review of AI at work associates consultation and training with better reported worker outcomes; it does not show that either step alone guarantees acceptance.
Tell every team what happens next
Announce the pilot to the whole affected group at the same time. State the workflow, selection rules, participating teams, dates, support available, measures, and the decision you will make at the end. Say whether people outside the pilot can offer examples or report risks. Give them a date for the next update even if the result may be “we need another test.”
Explain what early access means for nonparticipants. They still need normal tools, training, and manager attention. If the pilot succeeds, tell them how teams enter the next wave and what support comes with it. If you don't yet know the order, publish when you will decide it and who will take part in that decision.
Consider a service operation with three eligible teams. Two teams start a four-week pilot, while the third continues the current process. Tell all three why the first two were chosen, how you will compare completed cases, and when the third team can join if the result supports expansion. Share the same updates with everyone. Without that explanation, the waiting team can reasonably read the delay as a judgement about its people.
Handle comparison teams fairly
A team using the current process can help you judge whether a change came from the AI tool or from seasonal volume, new staff, or a simpler mix of cases. The UK government's guidance on evaluating AI interventions discusses comparison designs and the need to account for differences between groups. Choose a design that fits the work and be candid about what a small pilot cannot prove.
Do not withhold standard help from a comparison team. Give it the same baseline measurement, ordinary training, and access to managers. Keep the pilot's extra learning time visible when you compare costs. If you plan to offer the tool later, give the comparison team the date or condition for that decision. Ask whether waiting creates a material disadvantage; if it does, shorten the comparison or use a different measure.
Compare like cases through to completion. An assistant may draft a reply faster while a reviewer spends longer correcting it. Record the full handling and checking time, rework, customer outcome, and exceptions for both groups. Separate changes in the workflow from differences between the teams. A four-week test can reveal failures and promising signals, but it cannot settle every question about long-term adoption.
Report results and decide the next wave
At the end, publish the measures you promised and what staff said worked or failed. Include the time spent training, the cases the tool could not handle, and any change in quality. If the pilot selected confident volunteers or had unusually strong manager support, say so when you explain how far the result may apply.
Make an explicit decision: expand under defined conditions, repeat the test with a different team, change the workflow, or stop. Tell selected and waiting teams who owns the next step and when they will hear more. Close the loop with people who raised problems, including those whose suggestions changed the tool or the plan.
A fair pilot doesn't promise everyone the same start date. It gives people a clear reason for the order, support that lets them take part, and a credible way to shape what happens after the first test.